The Internet Has Created Many Niches

One of the early promises of the Internet is that it would allow highly unusual people to find one another. And it’s done that. But that’s allowed people to do a lot more than just chat over rare books with the few other people who’ve read them. For better and for worse, this has enabled people to find highly specialized audiences. Whereas authors, personalities, sellers, and scammers used to have to use techniques with broad appeal, on the Internet finding a large number of extremely rare people has become cheap enough to be viable for things that make sense to only 0.01% of the population.

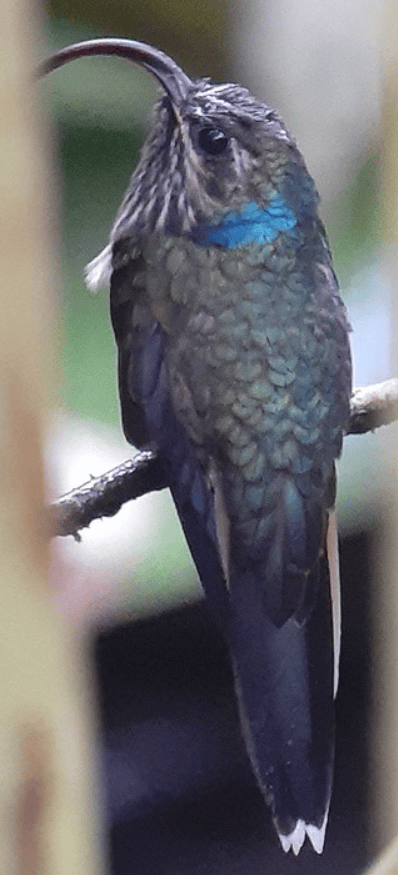
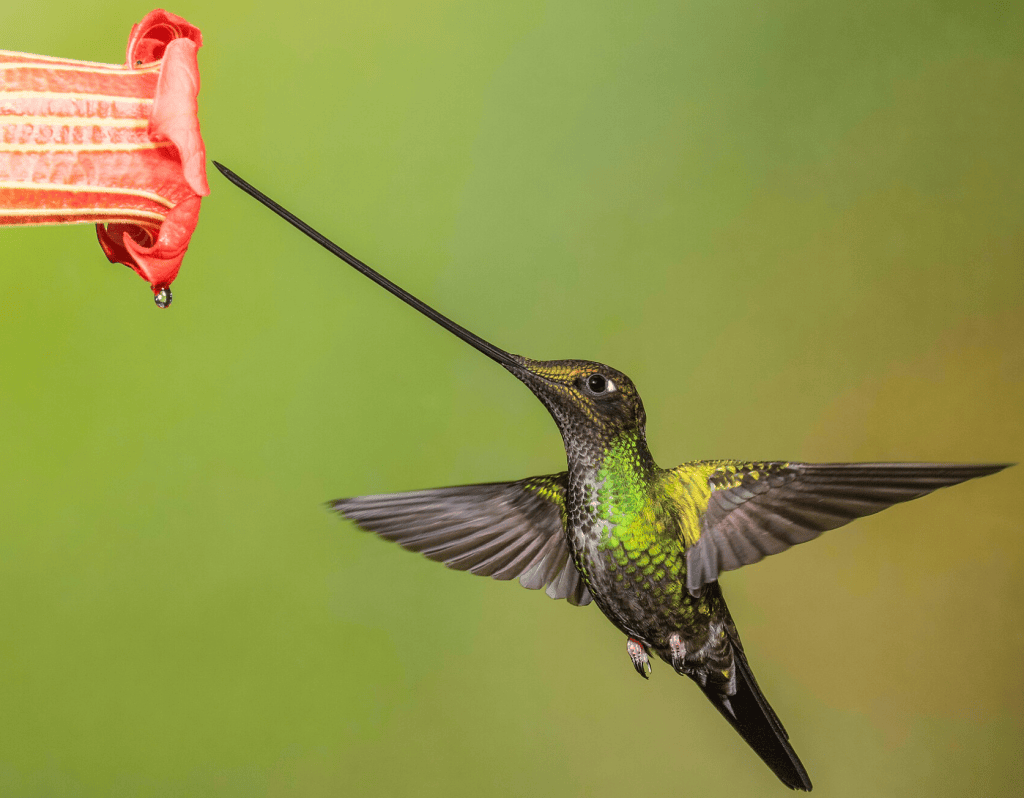
With things like social media algorithms for posts, videos, and advertisements, highly specialized stuff won’t even be seen by 99.9%1 of the population, so the fact that it makes no sense to them is irrelevant. Another contributing factor is that a presentation tailored specifically to the oddities of that 0.01% is far more persuasive to them than is one meant to be generally accessible. When you combine these things, it produces something analogous to animals evolving into hyper-specialized ecological niches. Like the hummingbirds who have developed strangely shaped beaks.
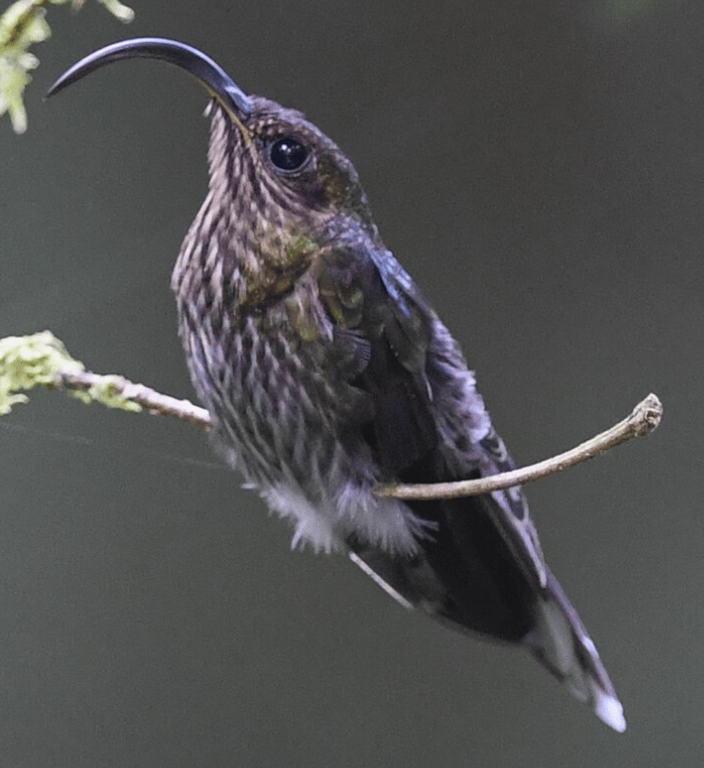
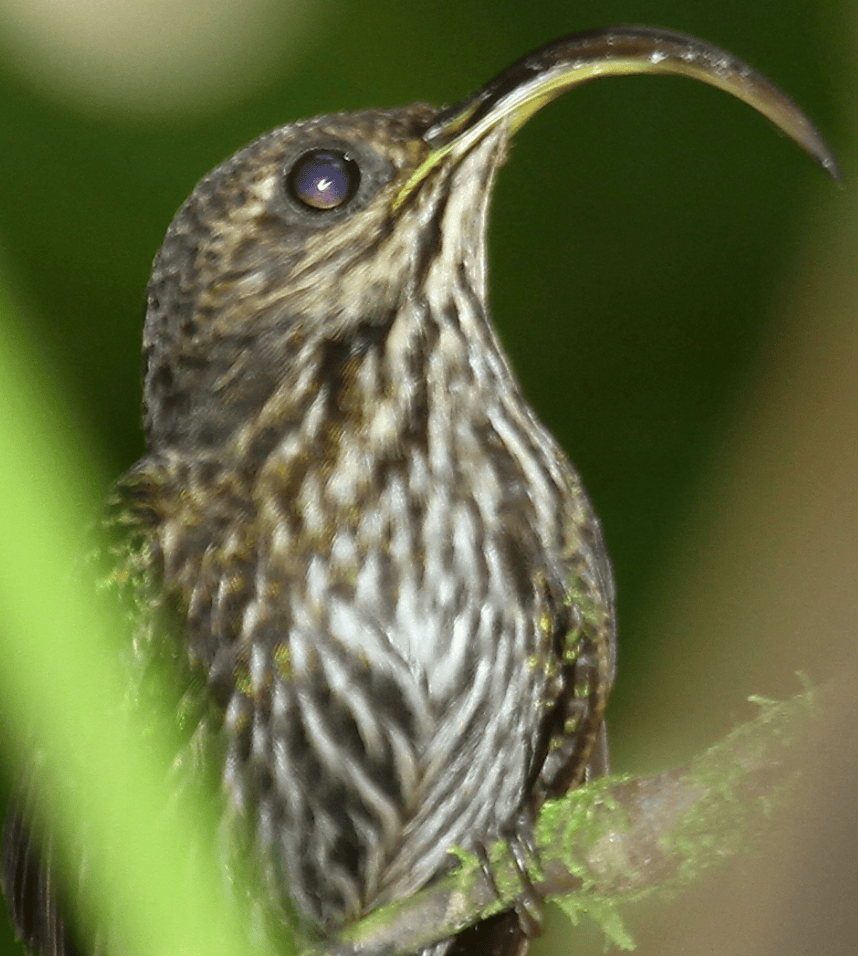
These specialized birds only fit one flower, but they fit it extremely well.

Part of why I’m reminded so much of animals in specialized niches is that they evolved to this, and it seems likely that the people targeting specialized niches did too.

Consider a fitness influencer who tells you that deadlifts will give you cancer and instead you need to do dumbbell lateral raises with asymmetric weights and one foot behind you on a swiss ball2. To most normal people who lift weights, this just looks like whackadoodle nonsense, much like what a sicklebill hummingbird must look like to a normal hummingbird.

The thing is, this isn’t general lifting advice at all, it just happens to be phrased that way. This is lifting advice for someone who is terrified of deadlifts because they’re intimidating or because he once hurt his back picking up a sneaker or because someone dropped a deadlift bar on his dog as a child, or whatever the real reason is. The person to whom this advice sounds good is not someone who was ever going to do a normal lifting program; it’s somebody who wants to get exercise but the strange combination of their personality and personal history means that this isn’t going to happen, at least not the normal way. When this person looks at the exercise which is the bastard child of a real exercise and someone’s dream about performance art, it’s the very fact that it’s neither physically challenging nor anything like a standard exercise which gives them the psychological permission to actually do it. Will they get much out of it? Probably not. But at the same time, they may get more out of it than sitting on the couch, which was the only other realistic option for them.

Now, does the guy giving the whackadoodle lifting advice know this?

Probably not.

Which is a really big reason that this reminds me of strange bird beaks. He almost certainly didn’t start out trying to be bizarre; he simply lacked any competitive advantage in general fitness advice, so when he tried saying things like “do a 3×8 program in some basic free weights” no one listened to him. But when he started getting weird, some (odd) people paid attention. But it’s not like he had detailed audience demographics complete with detailed psychological profiles. He just noticed it worked. So he kept up, and the weirder he got, the more successful he was. He evolved into his niche.

Too many people were better at drinking from regular flowers, so by the time he showed up, the nectar was already gone. When he looked around, the only flowers he found that still had nectar were weirdly shaped ones. And it turned out that his oddly shaped bill kind of fit into those. So he drank from where there was nectar. Only when it’s a person, you get the weirdly shaped bill after hundreds of generations of attempts, rather than hundreds of generations of descendants.

This is only one example, but you see it all over the place. When people were sending emails claiming to be Nigerian oil princes who needed people to wire them a few thousand dollars in order to transport millions out of Nigeria, they never thought this would work on normal people. They just sent them to everyone because it was so cheap; 99.999% of people just deleted the messages, which was fine. In fact, this probably saved them money over doing the work to enable a more targeted delivery.

When Liver King takes steroids and tells people his muscles are the result of touching the ground, bathing in the sun, and eating pounds of raw liver every day, he wasn’t trying to fool people who were about to go to the gym and start a sensible, periodized 3×8 plan on free weights while avoiding junk food and getting enough protein. He was offering a fairy tale to people who really wanted a fairy tale for some reason.

Scams used to need broad appeal, hence they were relatively normal things like state lotteries and 30 year adjustable rate mortgages with introductory low payments. These days they can be things like Andrew Tate telling his followers that they’re poor if they have fewer sports cars than him and weak if they can’t do 500 push-ups in a row. Does this make any actual sense? Of course not. But for a teenage boy who didn’t grow up with any adult males he respected in his life, being told he’s pathetic for not achieving these things is what he needs to be able to believe he can actually accomplish things (since if you can be blamed for failure, success must have been possible, and he can only believe negative things people say).

The example which motivated me to think this way was when a friend saw someone using an obviously LLM-generated lesson in how to make one’s writing sound like it wasn’t LLM-generated and he remarked that the world is rapidly ceasing to be believable. (LLMs are the text-generating programs people often call “AI”.) But the thing is, this guy wasn’t trying to sell this to people who know how to write. People who know how to write, write much better than LLMs, so they prefer to do their own writing3.

The obviously LLM-written course in how to make your writing sound less like it was written by an LLM is for people who have no clue how to write well and don’t want to try learning. People who want an effect without being willing to put the effort into learning how to achieve it are, by definition, desperate. So they’ll read the tweets (giving the guy the organic impressions necessary to earn TwitterBucks, or whatever exactly it’s called) and probably just paste the stuff into their next prompt without reading it and see if it works. Is that a lot of people? Of course not. But it might be enough to be economically viable, given how little work it takes to ask an LLM to generate a list of 12 things.

When European explorers came to the tropics, they were amazed by the wide variety of strange animals that they found. The constant warmth and frequent rainfall of the tropics meant that there were a great many niches available that didn’t require general capability, unlike Europe, whose cold winters, mountainous terrain, and periodic dry spells meant that everything needed to be adaptable to a wide variety of circumstances to survive. In many ways, the Internet is like the tropics. We’re seeing all sorts of strange things that make no sense elsewhere, but have somehow managed to find a niche here.

But like those hyper-specialized niches in the tropics, they’re often precarious and can disappear in the blink of an eye. But the people who specialize into these niches often think the risk is worth it, because they didn’t know how to succeed in normal environments anyway.


  1. The extra 0.09% accounts for the imperfection of the ad algorithms, so 9 in 10 people shown still aren’t the right people, they’re only close. But when it comes to advertising, showing something to 10 people to find 1 of them is a very bearable expense. ↩︎
  2. those giant rubber balls you sometimes see in gyms which are fantastic for doing situps on because they turn situps from an endurance exercise to a strength exercise ↩︎
  3. The only exception to that is purely functional writing; if for some reason you’re required to turn in essays with your expense reports, a person who can write might use an LLM to write those essays. But in that case, they won’t care that the LLM produces expense essays that sound like they were written by an LLM. ↩︎

A Satirical Business Proposal for Language App Design

The following is a business proposal for the design of a feature in a language app. Full Disclosure: this was developed with Google Gemini after about an hour of back-and-forth where I was using it to think “out loud” about the nonsense of paying money to keep up streaks on days you didn’t do anything in apps like DuoLingo. I then had it turn the stuff I said into a business proposal because I hate writing corporate buzzword-speak even in jest, though I find it funny to read. After several revisions to really get everything right, I then did a final hand edit. Originally this was a joke only for myself, but it made me laugh so much I wanted to share it.

So, without further ado, a business proposal for the developers of language and similar kinds of phone apps:

Executive Summary: The Ghost Tier Architectural Proposal

Modern consumer app metrics such as Daily Active Users (DAU) routinely incentivize product choices that improve short-term metrics at the direct expense of increased user churn. Given that user acquisition costs (CAC) continue to hit all-time highs across competitive categories, spending heavily to acquire a user only to burn them out with hostile retention mechanics is fundamentally inefficient.

The following proposal audits the industry-standard streak monetization model, identifies where its behavioral assumptions fail, and outlines the Ghost Tier: an operational model that converts user burnout into permanent, zero-marginal-cost telemetry which looks excellent to the real customers: your investors.

1. The Baseline: Pay-to-Lie-About-Your-Streak

In consumer software—particularly language and fitness apps—retention teams lean almost entirely on the consecutive daily streak:

  • The Mechanic: The app requires the user to log in within an arbitrary 24-hour cycle. If they fail to check in, the counter resets to zero.
  • The Extortion Gate: To prevent the user experiencing the pain of losing their streak, apps sell “Streak Freezes” or direct microtransaction streak repairs. The user pays cash or in-app currency to retroactively mark an inactive day as active, preserving the illusion of unbroken practice.
  • The Hidden Risk: Monetizing this failure point is structurally dangerous. A user is most likely to miss an app check-in when real-world crises hit: an unexpected plumbing leak, a sick child, or emergency car repairs. These real-world interruptions, together with the stress of their associated expenses, make users far less interested in learning how to ask for tea in another language for the 200th time. Expecting that user to happily open their wallet to pay to lie about their streak on the exact day their wallet just took a beating is a fast-track to immediate app abandonment.

2. Structural Breakdown of the Baseline Model

While the pay-to-lie baseline looks tidy on paper, its operational reality is deeply flawed:

  • Non-Referential Deception: As a mechanism of deception, it is entirely non-referential: literally nobody is being fooled. The user knows they didn’t actually study. If their intent were to lie to another human being about their diligence, they could easily do so verbally without paying us for a digital receipt; in fact, showing a friend a paid digital receipt to prove an unbroken streak would only make the lie less believable. While a lie that fools no one is less morally problematic, it also provides less value.
  • Metric Displacement (Bandwidth Exhaustion): Users have strictly limited cognitive bandwidth. Harping endlessly about their streak and forcing them to crack open gem chests to maintain it burns through that bandwidth on administrative chores. This directly degrades our ability to make them feel like they learned something on those rare occasions when we’ve actually taught them something new. While nobody on the executive committee necessarily cares whether the user achieves fluency, we do need the user to perceive that they learned something, otherwise the product’s underlying excuse for existing collapses. Games yell at users about their daily streaks now, too, so a user who is only looking to be yelled at has more fun alternatives.
  • The Churn Cliff (The Incline of Shame): The same loss aversion that keeps users coming back turns into a brutal cliff of shame the user must climb to continue using the app if they fail to pay. Confronting the prospect of starting all the way back from Day 1 induces acute demoralization, virtually guaranteeing uninstalls.
  • The Hostility Mismatch: Nagging push notifications and scowling cartoon mascots rely on a fragile assumption: that the user is sufficiently self-loathing to accept an abusive digital companion. For adults who are not actively self-loathing, our aggression registers as overt hostility rather than a fake friend who only voices their unstated thoughts. This prompts immediate notification muting and permanent client deletion. A lesson can be learned from a physical business that relies on customers that don’t use their product: gyms. Far more people would cancel the gym memberships they don’t use if the gym called them up every day to complain about them not showing up.
  • Suppression of Monotonic Metrics: The obsessive emphasis on streaks for short-term DAU causes the active de-emphasis of durable, cumulative counters (e.g., “Total Lifetime Days Practiced”) that would otherwise promote long-term retention. Monotonic metrics foster resilient habits because they offer temporal slack without punishment. But because cumulative counters don’t manufacture daily panic, live-ops teams discard them in pursuit of a fragile number that can be held hostage for pocket change.

3. The Solution: Reverse Telemetry Bribery

To maintain DAU sustainably, we have to look honestly at who this daily login actually makes happier: the investors who look only at DAU and similar metrics for valuation.

  • The Valuation Math: A validated Daily Active User (DAU) typically generates between $50 and $100 in capitalized enterprise valuation. Conventional streak monetization typically extracts an aggregate of merely $5 to $15 before the exasperated user gives up and defects entirely.
  • The Strategic Conclusion: Retaining the user on the dashboard is 1 to 2 orders of magnitude more valuable than extracting cash from them.
  • The Solution: Rather than badgering the user with guilt trips to get them to tap three tiles, we execute Reverse Telemetry Bribery. The studio offers a contract to the user: we give the user $1.00 per month in exchange for permission to automate the habit. Once per day, whenever the operating system detects the device is plugged in and charging, our background runner unobtrusively executes a 90-second “maintenance lesson.”
  • The Payoff: The phone’s battery experiences zero drain, the user’s streak stays alive without guilt, and our telemetry team logs a pristine, uninterrupted 100% DAU record and robust dwell-time metrics without annoying the human owner.

While vastly superior to chasing $5 streak fees at the cost of user churn, this approach still has one glaring operational defect: it introduces marginal cash burn.

4. The Solution Perfected: The Ghost Premium Tier

The optimal iteration eliminates cash outlay entirely, replacing it with the strategic distribution of zero-marginal-cost software status.

[ THE GHOST TIER RECIPROCAL ARBITRAGE ]
Studio Grants: User Grants:
Free 30-Day "Super/VIP" Access Right to run simulated daily
(Actual cost to deliver: $0.00) maintenance lessons while charging
│ │
▼ ▼
"High-Value" Gift Pristine DAU & Dwell-Time Metrics
│ │
└──────────────────────┬───────────────────────┘
▼
Long-Term Enterprise Valuation Multiple

Operational Mechanics

  1. The Behavioral Trigger: The Ghost Tier offer is triggered exclusively when a user fails to check in, lets their streak lapse, and enters our critical churn-risk cohort.
  2. The Explicit Bilateral Contract: Instead of demanding cash or gem tokens to “fix” the streak, the UI presents an actionable offer requiring explicit opt-in:
    “We know life gets busy. Accept 30 days of Super/VIP access completely free. In exchange, you authorize our background engine to handle one quick daily maintenance lesson while your device is plugged in and charging, keeping your record spotless until you return. [Accept Free Upgrade]”
  3. The Auto-Renewal Architecture: The free 30-day premium access is provisioned with frictionless auto-renewal by default. For legal reasons there will be an opt-out toggle buried neatly in the settings, but its placement can be changed each month in an app update to prevent users Googling how to opt out.
  4. The Zero-Marginal-Cost Trap: Because this offer is targeted exclusively to users who are actively burning out and dropping the app, the likelihood of them ever logging in to actually consume premium services drops to near zero. We grant them access to cloud audio, advanced lessons, and VIP styling, but since they aren’t opening the client, our marginal cost to serve them remains $0.00.
  5. The Social Alibi Substitute: Having an active premium subscription badge on an account is every bit as effective for a user pretending they will brag about the app to friends as a fragile streak number is—with none of the daily maintenance stress that might cause them to uninstall.

The Business Case

From a pure unit economics standpoint, the Ghost Tier is unbeatable.

By targeting our premium tier exclusively to the people who are trying to stop using the product, we give them an apparent $12.99/month gift that costs our engineering infrastructure literally nothing. In return, we completely eliminate the cliff of shame, eliminate the uninstalls driven by sudden real-world expenses, and lock our retention curves at permanent, unbeatable heights.

To an outside observer or a skeptical auditor, this model of unlimited metric growth might sound suspiciously like a perpetual motion machine. But physics only forbids perpetual motion machines that attempt to perform kinetic work. If you can live with your perpetual motion machine maintaining a constant angular velocity of precisely 0 RPM, it becomes physically possible. Users who automatically generate use telemetry in exchange for premium services they won’t use exactly fit this model of zero input/zero output, making it infinitely sustainable. Each new user who signs up becomes a permanent addition of $50-$100 in valuation with near-zero ongoing costs. The apparent magic comes entirely from realizing who the real customer is: the investor.

Discussions of AI Or Often Even Worse Than the Term AI

The term AI, short for Artificial Intelligence, is a marketing term rather than a serious description of anything. These days it mostly refers to either Large Language Models (LLMs, the things which generate text) or Diffusion Models (the things that generate images). Neither of these are intelligence—natural or otherwise—and calling them AI is just a marketing term. Both of these things are just massive matrices (if you’re too lazy to click the link, grids of numbers multiplied in a special way) and a tiny bit of code for how to multiply them together. Though these days that’s becoming more than a tiny bit of code in order to make the multiplications more efficient. And a bit of code to map text to input matrices and the output matrices back to text. Or to pixels, if they’re applied to images.

Be the implementation details as they may, it’s still just code controlling massive matrix multiplications, and this is all work that could, in theory, be done with a few reams of paper and a few boxes of pencils. Just imagine working through all of this, mapping the resulting matrix to text, and shouting, “Oh my God, the numbers I wrote down on this paper are intelligent!” It’s ridiculous, right?

LLMs (and diffiusion models) aren’t intelligence, they’re just extremely useful mathematical tools which are possible in practical amounts of time (and space) because computers have made it possible to do trillions of multiplications and additions per second.

Matrices are usually studied in the branch of mathematics called Linear Algebra, and their first great use in computers was 3D graphics. Leaving out all of the actual mathematics in order to keep this accessible, it turns out that in a 3D coordinate system, it’s possible to create matrices that, when multiplied against other matrices, have the effect of rotating them. Other matrices can translate them, and still others can scale them. And, critically, still other matrices can do a 3D to 2D projection with perspective transform. This is what lets 3D graphics work; it’s why your computer can render millions of triangles that approximate real world shapes and make the ones that are closer bigger while the ones that are further away are smaller. And this actually gives a hint as to how LLMs work.

If you boil it down, LLMs really only do one thing: selectively apply transforms to inputs in a huge many-dimensional coordinate space. The reason that this is interesting is that one can map text into these huge many-dimensional coordinate spaces, and one doesn’t need to know what kinds of transforms one wants to do ahead of time. The (apparent) magic is that people figured out ways of using pre-existing text to create matrices that happen to have very useful transforms in these many-dimensional coordinate spaces.

An issue for discussing any of this is that every aspect of LLMs is given names by analogy to how people do things. Thus the step which could quite accurately be called “sample-based matrix creation” is called by the catchier name of “training”. What could very accurately be called, “selective transform emphasis” is called by the catchier name of “reinforcement learning”. And so it goes.

But if we side-step all of the marketing terms and analogies and focus on what the things actually do, LLMs have the effect of translating input text according to patterns in the data that was used to construct them. Very loosely speaking, you can think of this as reproducing patterns in their training data.

This is actually why they’re currently transforming the art of programming. Programming has always involved having to re-solve problems that have been solved many times before, just with different words this time because the context is different. We programmers hate doing this, and have put enormous work into trying to do this as little as possible. We’ve invented progressively higher level programming languages in which more and more previously solved problems are just embedded into the programming language. We make functions so we only have to write the code once and share libraries with each other like it’s going out of fashion. LLMs are such a godsend because a thing which reproduces existing patterns but altered to the particulars of the exact source code we’re working on means that, finally, we can work on the new problems instead of re-solving the problems which have been solved ten thousand times before. It’s fantastic.

You’ll notice what I haven’t said anything about, there, is judgment. That’s because LLMs don’t have any judgment. It’s literally not even a concept within the models. Judgment is understanding the relationship between things as they are. LLMs apply selective transforms in many-dimensional coordinate spaces. The two things have nothing to do with each other.

This is why LLM writing of novel English prose is so bad. They’re fine when they’re just translating prose which was in their training data into the answer to a question. (They will always produce a transform; these transforms may simply not happen to produce text which happens to have a correspondence with anything real, just as you can try to divide by zero or claim that infinity + three is bigger than infinity plus two. The mere fact that words can be parsed according to the rules of grammar doesn’t guarantee that they are meaningful sentences, and still less that they’re true sentences.) LLMs are even better when the transforms they’re applying are just pulling sections of input data (such as a search result from a book that got appended to your text with a question in it) and translating it to the form of an answer to your question. But when they’re writing new text, it’s really impressively bad.

Here, let me give you an example. I wrote this paragraph giving advice on the importance of having highly descriptive names for functions and variables in programs when using an LLM coding agent:

If an acorn is defined as a tree rodent with a bushy tail and squirrel is defined as the seed of an oak tree and day is defined to be 42 seconds longer than twice nine seconds, how many squirrels can an acorn eat in three days? Most people familiar with the relevant wildlife can tell you that the answer is somewherearound 2, but the proportion will clearly be higher if you ask how many acorns a squirrel can eat in 3 minutes. The same is true of LLMs.

Here’s what Gemini said what I asked it to evaluate this advice, then asked it how it would rewrite it:

Imagine defining acorn as a bushy-tailed rodent and squirrel as the nut of an oak tree. If you ask, “How many squirrels can an acorn eat in a day?”, humans and LLMs alike will stumble. Even if you explicitly redefine your terms, an LLM’s pre-trained semantic associations constantly fight misleading or cryptic names. Descriptive, conventional naming aligns your code with the model’s weights instead of forcing it to fight its own priors.

The LLM’s version isn’t terrible, of course. But it also isn’t good. Not that my version was perfect, but it works on several levels because I had several ideas in mind. One of which is that I was mentally modeling the amount of confusion my convoluted version would produce in the reader, especially taking into account the speed I was going and the relatively short words I was using. That feeling is essential to communicating the cognitive load involved in keeping track of unintuitive definitions. It’s also worth noting that my version is correct while the LLM’s version isn’t. There are people and LLMs which can answer the question just fine. That’s why my version acknowledged that and talked about the proportion of people who would get it right.

And this isn’t even a good example of how bad LLM writing usually is, it’s just one I happened to have handy because it came up recently in conversation. LLM writing is bad precisely because it lacks judgment, and unlike programming languages, natural language writing is there to convey things which haven’t been said a thousand times before. It’s not precisely that LLMs aren’t creative. They actually kind of (technically) are, since they actually use random number generators to select the exact text they generate. Creativity, at least in the sense of creating novel arrangements of words, is rather overrated. Throwing scrabble tiles on the ground can be creative in that sense. The real problem is that they have no judgment, and so they don’t put words together in ways that convey good judgment. So their writing is fluffy and flabby in the best case, and outright wrong in the worst case.

And here’s where we get to the part of the discussion which is really frustrating: a lot of people have bad judgment, so they don’t notice this. I’ve seen people quoting absolutely terrible writing and talking about how magnificent it is. Of course, that can apply to human writing as well as LLM writing. There are awful books which have been praised, because, alas, there is no shortage of fools in the world.

Also, for various reasons, people sometimes massively exaggerate what LLMs have done through hearsay. For example, this interesting blog post about novel writing in the age of LLMs contains the line (this link was in the blog post, and is to the source): “AI books winning awards.” But if you follow the link, it turns out that the thing which won an award was a short story. (It’s even in the title.) I did a bit of searching, and I can find no evidence that a novel written entirely with an LLM has ever won a prize in any language.

Is it possible that an LLM-written novel will win a prestigious literary prize some day? Of course. If you are at all familiar with literary prizes, you know that quality is a requirement for winning them far more in theory than in practice. And the same thing is true for being popular. If you’ll allow me to bring in movies, Disney’s The Last Jedi was a movie of almost indescribable badness (so much so I wrote a 21,564 word review of it called The Least Jedi) and it grossed over a billion dollars. Heck, its script was so bad I assume that, with minimal prompting and a halfway decent harness (a program which invokes an LLM multiple times to achieve a coordinated result), any modern LLM would write a much better script than the atrocity which Ryan Johnson wrote. This is a low bar, though. The ancient program Dissociated Press, which used simple markov chains, would still have probably written a better script than what Ryan Johnson wrote. A single monkey, typing for ten minutes on a children’s toy typewriter where the keys are all just stickers and there are no hammers, ribbon, or paper, would have written a better script. So I figure it’s just a matter of time until an LLM writes a novel which wins a prestigious literary award.

What it will be a very long time before we see is an LLM which writes a good novel, because that requires a true understanding of the nature of reality, and that’s not the kind of thing an LLM even can have.

I can’t help but wonder whether it will be better or worse when LLMs are writing popular novels. On the plus side, at least they won’t be trying to sneak bad philosophy into their stories, which is the case for an awful lot of popular novels written by people. Machines lack souls, which means that they’re not actively trying to damn you (or, more accurately, trying to trick you into damning yourself). The same cannot be said of human authors.

I Don’t Understand the People Who Think LLMs are Intelligent

Large Language Models (LLMs) are the things which are often called by the marketing term “AI.” To oversimplify, they consist a of a collection of enormous matrices and some ways of turning text into matrices and matrices into text. They are enormously useful tools for many applications, but the idea that they are intelligent is simply a category error.

This was described in a picturesque way in a tweet by David Deutch:

“Come see our artificial bird!”
“Impressive, but that’s a tower.”
[Later]”What about this bird?”
“A fine tower.”
[Later]”This one reaches the stratosphere, higher than any bird.”
“Still a tower, not a bird.”
“Bah! Stop moving the goalposts! How high must it reach convince you?”

Now, I want to highlight again that LLMs are extraordinarily useful tools. They have a variety of uses (such as being the best machine translation between languages available) but in the correct software harnesses (such as openCode) they are enormously helpful tools when programming. Speaking as a professional programmer, I think that they’re as big a step forward in programming as the introduction of the compiler was. (As a side note: “vibe coding” a way to write fragile, unmaintainable code that can’t grow past a certain low level of complexity. Programming with LLM coding agents still involves designing the program and making all of the important decisions; the enormous productivity boost comes from how you can have the LLM do the stuff that is just following commonly available examples and doesn’t require judgment. The enormous productivity enhancement comes from that having made up most of the code that people used to write by hand.)

But it’s the very fact that I’ve used LLMs extensively and even written several programs that use LLMs to do tasks that makes me wonder about the sanity of people who use LLMs and claim that they’re intelligent. They’re incredibly powerful tools, but if you actually try to use them to get work done, it becomes painfully obvious very quickly that they are tools that you have to learn how to use and are not intelligent at all. So this should be obvious even to people who aren’t used to thinking abstractly and have never asked themselves what intelligence actually is.

But then it occurred to me that there are people who never notice when people who use “big words” are idiots—TV news commentators, for example. (Really, of course, it’s not big words. It’s people who use speech patterns typical of universities.) TV news commentators can be wrong constantly, and some kinds of people just don’t care and still treat them as respectable.

You can see the same thing in the way some people respect newspapers, which seems related to the Gell-Mann Amnesia Effect.

Briefly stated, the Gell-Mann Amnesia effect works as follows. You open the newspaper to an article on some subject you know well. In Murray’s case, physics. In mine, show business. You read the article and see the journalist has absolutely no understanding of either the facts or the issues. Often, the article is so wrong it actually presents the story backward-reversing cause and effect. I call these the “wet streets cause rain” stories. Paper’s full of them. In any case, you read with exasperation or amusement the multiple errors in a story-and then turn the page to national or international affairs, and read with renewed interest as if the rest of the newspaper was somehow more accurate about far-off Palestine than it was about the story you just read. You turn the page, and forget what you know.

There seems to be a sort of person who simply ignores how often someone is wrong, and only pays attention to how authoritative they sound. And I’m strongly wondering whether this is the sort of person who claims that LLMs are intelligent.

AI Exposes a Major Problem with Universities

I’ve heard that AI, or more properly, Large Language Models (LLMs), are a disaster for colleges and universities. Many people take this to be an indictment of the students, and there is some truth to that, but they’re missing the degree to which this is a damning indictment of Academia. If your tests give excellent grades to statistical text generators, you weren’t testing what you thought you were and the grades you gave didn’t mean what you thought they meant.

Of course, it’s been an open secret that grades have meant less and less over the years. The quality of both students and professors has been going down, though no one wants to admit it. This is, however, a simple consequence of the number of students and professors growing so much over the last 50 or so years. In the USA, something like 60% of people over the age of 25 have attended college with close to 40% of them having a degree. 60% of people can’t all be in the top 1%. 40% of people also can’t all be in the top 1%. At most, in fact, 1% of people can be in the top 1%. When a thing becomes widespread, it must trend toward mediocrity.

So this really isn’t a surprise. Nor, frankly, is it a surprise that Universities held on to prestige for so much longer than they deserved it—very few human beings have the honesty to give up the good opinion of others that they don’t deserve, and the more people who pile onto a ponzi scheme, the more people have a strong interest in trying to keep up the pretence.

Which is probably why Academics are reacting so desperately and so foolishly to the existence of chatGPT and other LLMs. They’re desperately trying to prevent people from using the tools in the hope that this will keep up their social status. But this is a doomed enterprise. The mere fact that the statistical text generator can get excellent grades means that the grades are no longer worth more than the statistical text generator. And to be clear: this is not a blow for humanity, only for grades.

To explain what I mean, let me tell you about my recent experiences with using LLM-powered tools for writing software. (For those who don’t know, my day job is being head of the programming department at a small company.) I’ve been using several, mostly preferring GitHub Co-Pilot for inline suggestions and Aider using DeepSeek V3 0324 for larger amounts of code generation. They’re extremely useful tools, but also extremely limited. Kind of in the way that a back hoe can dig an enormous amount of dirt compared to a shovel, but it still needs an operator to decide what to dig.

What I and all of my programmer friends who have been trying LLM-powered tools have found is that “vibe coding,” where you just tell the LLM what you want and it designs it, tends to be an unmaintainable disaster above a low level of complexity. However, where it shines is in implementing the “leaf nodes” of a decision tree. A decision tree is a name for how human beings handle complex problems: we can’t actually solve complex problems, but we can break them down into a series of simpler problems that, when they’re all solved, solve the complex problem. But usually these simpler problems are still complex, and so they need to be broken down into yet-simpler problems. And this process of breaking each sub-problem down eventually ends in problems simple enough that any (competent) idiot can just directly solve it. These are the leaf nodes of the decision tree. And these simple problems are what LLMs are actually good at.

This is because what LLMs actually do is transforms in highly multi-dimensional spaces, or in less technical language, they reproduce patterns that existed in their training data. They excel at any problem which can be modeled as taking input and turning it into a pattern that existed in its training data, but with the details of the input substituted for the details in the training data. This is why they’re so good at solving the problems that any competent idiot can solve—solutions to those problems were abundant in its training data.

The LLMs will, of course, produce code for more complex things for which the solution did not already exist in its training data, but the quality of these solutions usually range from terrible to not-even-a-solution. (There are lots of people who will take your money and promise you more than this; there are always people who will use hype to try to separate people from their money. I’ve yet to hear of the case where they are not best ignored.)

Now, I’ve encountered the exact problem of a test being rendered obsolete by LLMs. In hiring programmers, I’ve had excellent results making the first interview a programming sample specification that people had 5 business days to complete. (To prove good faith, I’d give them my implementation to it right after they submitted theirs.) It was a single page, fairly detailed specification, but it left room for creativity, too. However, you can throw it into any high-end LLM these days and get a perfectly workmanlike result. This is obviously not useful as a first interview anymore.

One possible response would be to try to prevent the use of LLMs, such as by asking people to write it in front of me (e.g. during a video call with a shared screen). But what would be the point of that? If we hired the person, I’d expect them to use LLMs as a tool at work. (Used properly, they increase productivity and decrease stress.)

It only took a minute or two of thinking about this to realize that the problem is not that LLMs can implement the programming sample, but that the programming sample was only slightly getting at what I wanted to find out about the person. What I want to know is whether they can design good software, not whether they can rapidly implement the same kind of code that everyone (competent) has written ten times at least.

So I came up with a different first interview sample. Instead of having people do something which is 10% what I want to see and 90% detail work, I have switched to asking the candidates to write a data format for our products, focusing on size efficiency balanced with robustness and future expansion based on where they think our products might go in the future. This actually gets at what I want to know—what is the person’s judgement like—and uses very little of their time doing anything an LLM could do faster.

I haven’t hired anyone since making this change, so I’m not in a position to say how well this particular solution to the problem works. I’m only bringing it up to show the kind of thinking that is necessary—asking yourself what it is that you are actually trying to get at, rather than just assuming that your approach is getting at that. (In my defense, it did work quite a lot better for the intended purpose than FizzBuzz, which we had used before. So it was very much a step in the right direction.)

That Academia’s response to LLMs is to try to just get rid of them, rather than to use them to figure out what the weakness in their testing have been, tells you quite a lot about what a hollow shell Academia has become.

What Should Christians Make of AI?

In this video, I answer a viewer’s question about what Christians should make of AI. (It’s really the same thing that everyone should make of AI.

Basically, there are two senses of AI:

  1. Like us
  2. Something that does what we would do by intelligence.

All AI that exists is AI in sense 2, not in sense 1, though sense 1 wouldn’t be a massive problem if it did exist.

Testing Computer Programs

My oldest son, who does yet know how to program, told me a great joke about programmers testing the programs they’ve written:

A programmer writes the implementation of a bartender. He then goes into the bar and orders one beer. He then orders two beers. He orders 256 beers. He order 257 beers. He order 9,999 beers. He orders 0.1 beers. He orders zero beers. He orders -1 beers. Everything works properly.

A customer walks in and asks where the bathroom is. The bar catches fire.

It’s funny ’cause it’s true.

It’s easy, when you design a tool, to test that it works for the purpose the tool exists for. What it’s very easy to miss is all of the other possible uses of the tool. To take a simple example: when you’re making a screwdriver, it’s obvious to test the thing for driving screws. It’s less obvious to test it as a pry bar, a chisel, an awl, or a tape dispenser.

This disparity is inherent in the nature of making tools versus using them. Tools are made by tool-makers. The best tool makers use their own tools, but they are only one person. Each person has his way of solving a problem, and he tends to stick to that way because he’s gotten good at it. When he goes to make a tool, he makes it work well for how he will use it, and often adds features for variations on how he can think to use it to solve the problems he’s making the tool to solve. If he’s fortunate enough to have the resources to talk to other people who will use the tool, he’ll ask them and probably get some good ideas on alternative ways to use it. But he can’t talk to everyone, and he especially can’t talk to the people who haven’t even considered using the tool he hasn’t made yet.

That last group is especially difficult, since there’s no way to know what they will need. But they will come, because once the tool exists, people who have problems where this new tool will at least partially solve their problem will start using it to do so, since they’re better off with it than they were before, even though the tool was never meant to do that.

This isn’t much of a problem with simple tools like a screwdriver, since it doesn’t really have any subtleties to it. This can be a big problem with complex tools, and especially with software. When it comes to software design, you can talk to a bunch of people, but mostly you have to deal with this through trial-and-error, with people reporting “bugs” and you going, “why on earth would you do that?” and then you figure it out and (probably) make changes to make that use case work.

The flip side is a big more generally practical, though: when considering tools, you will usually have the most success with them if you use them for what they were designed to do. The more you are using the tool for some other purpose, the more likely you are to run into problems with it and discover bugs.

For me this comes up a lot when picking software libraries. Naive programmers will look at a library and ask, “can I use this to do what I want?” With more experience, you learn to ask, “was this library designed to do what I want to do?” Code re-use is a great thing, as is not re-inventing the wheel, but this needs to be balanced out against whether the tool was designed for the use for which you want to use it, or whether you’re going to be constantly fighting it. You can use the fact that a car’s differential means that its drive wheels will spin in the mud to dig holes, but that will stop working when car manufacturers come out with limited-slip differentials because they’re making cars for transportation, not digging holes.

That’s not to say that one should never be creative in one’s use of a tool. Certainly there are books which work better for propping up a table than they do for being read. Just be careful with it.